FitFuel
AI Product Design Student Project
Solo UX researcher and designer
Role
Applied case study for a fictional early-stage startup
Project Type
Timeline
3 weeks
Claude (research, drafting, and documentation)
Figma Make (interactive prototyping)
Lighthouse (accessibility scanning)
axe DevTools (accessibility scanning)
Tools
Primary research report
Personas
Journey map
Decision-ready design package
Interactive prototype
WCAG 2.2 AA accessibility audit
Deliverables
FitFuel is a fictional AI-enhanced fitness and nutrition app, built as a three-week applied case study for an early-stage startup. The team had a hypothesis, not a validated strategy: that busy professionals might be an underserved audience for a more adaptive kind of fitness support. They wanted AI to play a real role in the product, adaptive planning, progress insights, supportive copy, not just tracking, and they wanted every decision behind it professionally defensible. The product space touched workout planning, nutrition support, habit formation, and accountability. They were also genuinely willing to change direction if the research didn't support their idea.
Context
I led this project solo: research direction, primary research, synthesis, opportunity mapping, a decision-ready design package, and a WCAG 2.2 AA accessibility audit. I worked from interview transcripts the client had already collected, using Claude as a research and production partner throughout, though every decision that shaped the product stayed mine. I designed and prototyped the adaptive planning flow as an interactive experience in Figma Make. Two commitments anchored the work: every insight carried a validation status, and every reversal got documented rather than smoothed over.
Role
Research reframed the brief entirely: the real barrier to consistency wasn't motivation but capacity, and people were disengaging in a sharp boom-bust pattern rather than a slow fade. That led to a focused opportunity, Adaptive, Context-Responsive Planning.
I produced an interactive prototype and design package with a fully traceable line back to the research, including a transparent account of what's proven and what's still open.
Results
The Problem
The client came in with a belief, not a validated strategy. They suspected busy professionals were an underserved audience for a more adaptive kind of fitness support, and they wanted AI to play a real role in that: adaptive planning, progress insights, supportive copy, not just step tracking. What made this a real design challenge, and not just a build job, was what they asked for alongside the idea. They wanted the work professionally defensible: no unsupported market claims, no unchecked AI output, no narrow default personas, no design rationale that couldn't be traced back to evidence. They were also genuinely willing to change direction if the research didn't support their hypothesis.
That combination put the burden on research to actually settle the question before design started. Before jumping into designing a fitness app, my job was to find out:
• Was “busy professional” a real, underserved segment, or just a comfortable default?
• Was the actual barrier to consistency time, or something closer to motivation, confidence, or health constraints that a generic fitness app never asks about?
• Did personalization need to respond to a stated goal, or to the shape of someone's actual day?
• What would make AI involvement in a health decision feel trustworthy instead of invasive?
• Whose needs were the default fitness-app assumptions quietly leaving out, older users, disabled users, people returning after injury, people outside conventional body-goal narratives?
The central tension: the client's confidence in the busy-professional hypothesis was outpacing the evidence for it. My job was to close that gap before it shaped a product built for the wrong person.
The Process
I brought a collaborative, evidence-based process to this project. Two commitments anchored all four weeks:
• Every insight carries a validation status. Findings were tagged Validated (grounded in primary research), Partially Validated, Practitioner Judgment, or External Evidence. External benchmarks never quietly borrowed the credibility of validated research. Hypotheses only made it into final deliverables when they pointed toward a specific next research step, not just to show my work.
• Reversals get named out loud. When I changed a decision, whether renaming a persona, removing an unsupported income assumption, or splitting a hypothesis that turned out to be blending two different people, I documented the change and the reasoning behind it. I didn't smooth it into a tidy final version.
Claude was my primary AI collaborator across every phase of this project: research synthesis, first-pass persona and microcopy drafting, structuring the accessibility audit findings, and later assembling final documentation. I built my workflow around a prompt library, and I tailored each prompt to the specific outcome I was after before I submitted it. Every prompt required a validation log and a source trail for each claim, so I could check the work instead of taking it at face value. I also instructed Claude to push back on my questions and assumptions, which helped me catch any weak reasoning early and kept the final results grounded in evidence. Throughout the way I kept documents of each step to maintain the data and discoveries.
AI never functioned as a source of truth. The decisions that actually shaped the product stayed mine: what counted as evidence, what got prioritized, what got reversed.
Research combined AI-assisted desk research with primary interview analysis, run through structured prompt sequences rather than open-ended requests. For each phase, market scoping, competitive identification, feature and sentiment analysis, thematic synthesis, and persona refinement, I ran the lesson's specified prompts in sequence and reviewed each output before moving to the next step.
I also directed several concrete course corrections along the way: confirming which competitors warranted deep attention, excluding wearables from the competitive set, requesting that user and practitioner interview data be analyzed separately rather than pooled, and commissioning a clustering-failure audit on the thematic synthesis (checking for over-clustering, under-clustering, surface clustering, and mismatched theme names) that led to real revisions, not a pass/fail formality.
To rapidly convey ideas post-research stage, I was tasked with creating a stakeholder presentation in Gamma to concisely convey the rationale behind my discoveries thus far in a quick but professional way.
Research
Immersing myself in the data surfaced patterns that changed the brief in genuinely useful ways. None of these held up as a single, tidy finding on the first pass. Each one sharpened, or in some cases split apart, once I pushed the synthesis harder than a first read would have.
Boom-bust cycling. Three of five interviewees described an identical pattern: starting hard, then dropping off completely, rather than gradually drifting away. That's a different design problem than a slow fade. I kept it as its own theme rather than folding it into the broader "life gets in the way" story, because the fix people proposed themselves, a small session that still counts as a full win, showed up independently across all five.
Tired, not lazy. The barrier people described wasn't a lack of motivation. It was capacity: energy, bandwidth, the real cost of showing up. All five interviewees said some version of it. I initially let that read as one clean insight, until I ran a clustering audit on my own synthesis and found it was flattening four different root causes, a chaotic schedule, structural overload from caregiving, cognitive unpredictability, and physical illness, into a single "tired" label. Those four causes don't all take the same design fix.
Trustworthy AI. People had a specific, describable line for what made AI feel like a helpful presence versus an overstepping one: explain its reasoning, default to caution when unsure, hand off to a human for anything injury- or mental-health-adjacent. I'd initially credited some of that specificity to the two practitioners in the sample. When I asked for user and practitioner data to be separated and re-checked, it turned out users had articulated those same conditions in their own words, which meant the trust requirement was user-validated, not borrowed from expert framing.
Nutrition-specific patterns. What first looked like one shared preference for "light-touch" nutrition guidance turned out to be four different people avoiding food tracking for four different reasons: eating-disorder safety, decision fatigue, a bad past experience, and a screen-reader accessibility barrier. I only caught that once I asked whether the theme had been clustered by topic instead of by actual motivation, the same design instinct held (don't force tracking) but with a much more specific set of reasons behind it.
Insights
I began with interview transcripts the client had already collected, which gave me primary access to real user language instead of guesses. I uploaded the five target user interview transcripts directly to Claude and gave detailed instructions on how to draft the persona document.
Once the persona and journey map artifacts were drafted, I reviewed, exported, and edited the persona deck by hand in PowerPoint, adding a photograph to each profile and relabeling fields before treating the deck as final and folding it back into the consolidated report. I used Adobe Firefly to create the images, since they pull from stock photos and are safe for licensing. Even at a drafting stage where it wasn't strictly necessary, my own AI ethics policy carries here: I don't pull images from individuals whose likenesses were used as training data without their consent.
Sections initially included, such as income, were left blank. Despite my ability to look up the median salary for each persona's specified field, I chose not to fabricate that detail into the personas based on information the interviews themselves didn't provide. This is something worth revisiting later, when the project reaches the point of establishing the financial dimension of app execution, but it isn't an immediate concern at this early stage.
Persona Development
Persona development stayed grounded in the transcripts, not generic fitness-app archetypes. Every trait and behavioral cue traced back to something a real interviewee said. That discipline surfaced two catches:
Catching an averaged persona. What I'd initially called the "Returning Routine Builder" turned out to be two mechanically different people I'd unintentionally blended into one. Splitting them apart was a bias check I ran on my own synthesis, not a client note, and it's exactly the kind of catch that keeps a persona from quietly steering design toward someone who doesn't actually exist.
Removing an unsupported income assumption. An early persona draft included income estimates that read as plausible detail. When I checked them against the transcripts, no interview had actually disclosed income. I pulled the estimates rather than leave them in because they "felt right."
Three personas carried forward:
Jordan Reyes (primary), shaped directly by the boom-bust cycling pattern.
Renee Marsh, refined as her motivations became clearer through the transcripts.
Theo Alvarez (edge-case), whose screen-reader-first needs made the accessibility work later feel essential rather than procedural
I asked for the journey map to follow a 5×5 framework made from five stages (Awareness, Consideration, Onboarding, Core Use, Retention) crossed with five attributes (Actions, Thoughts, Emotional State, Pain Points, Opportunities). That specificity mattered. A generic journey map format would have let vague, generic pain points slip through; naming five deliberate attributes per stage forced every entry back to something the research actually supported.
Jordan Reyes was the right choice for this first map, and not by default. Jordan represents the busy professional segment that was the project's original starting hypothesis, so grounding the first journey map in that persona kept the deliverable tied to the brief's own priorities rather than drifting toward whichever persona happened to be most colorful. More importantly, Jordan's defining pattern (a fixed plan breaking against an unpredictable week) was the single most validated finding across the entire research set, appearing independently in all five user interviews. Mapping her journey meant every stage of the map connected back to the strongest evidence I had, not the thinnest.
Journey Mapping
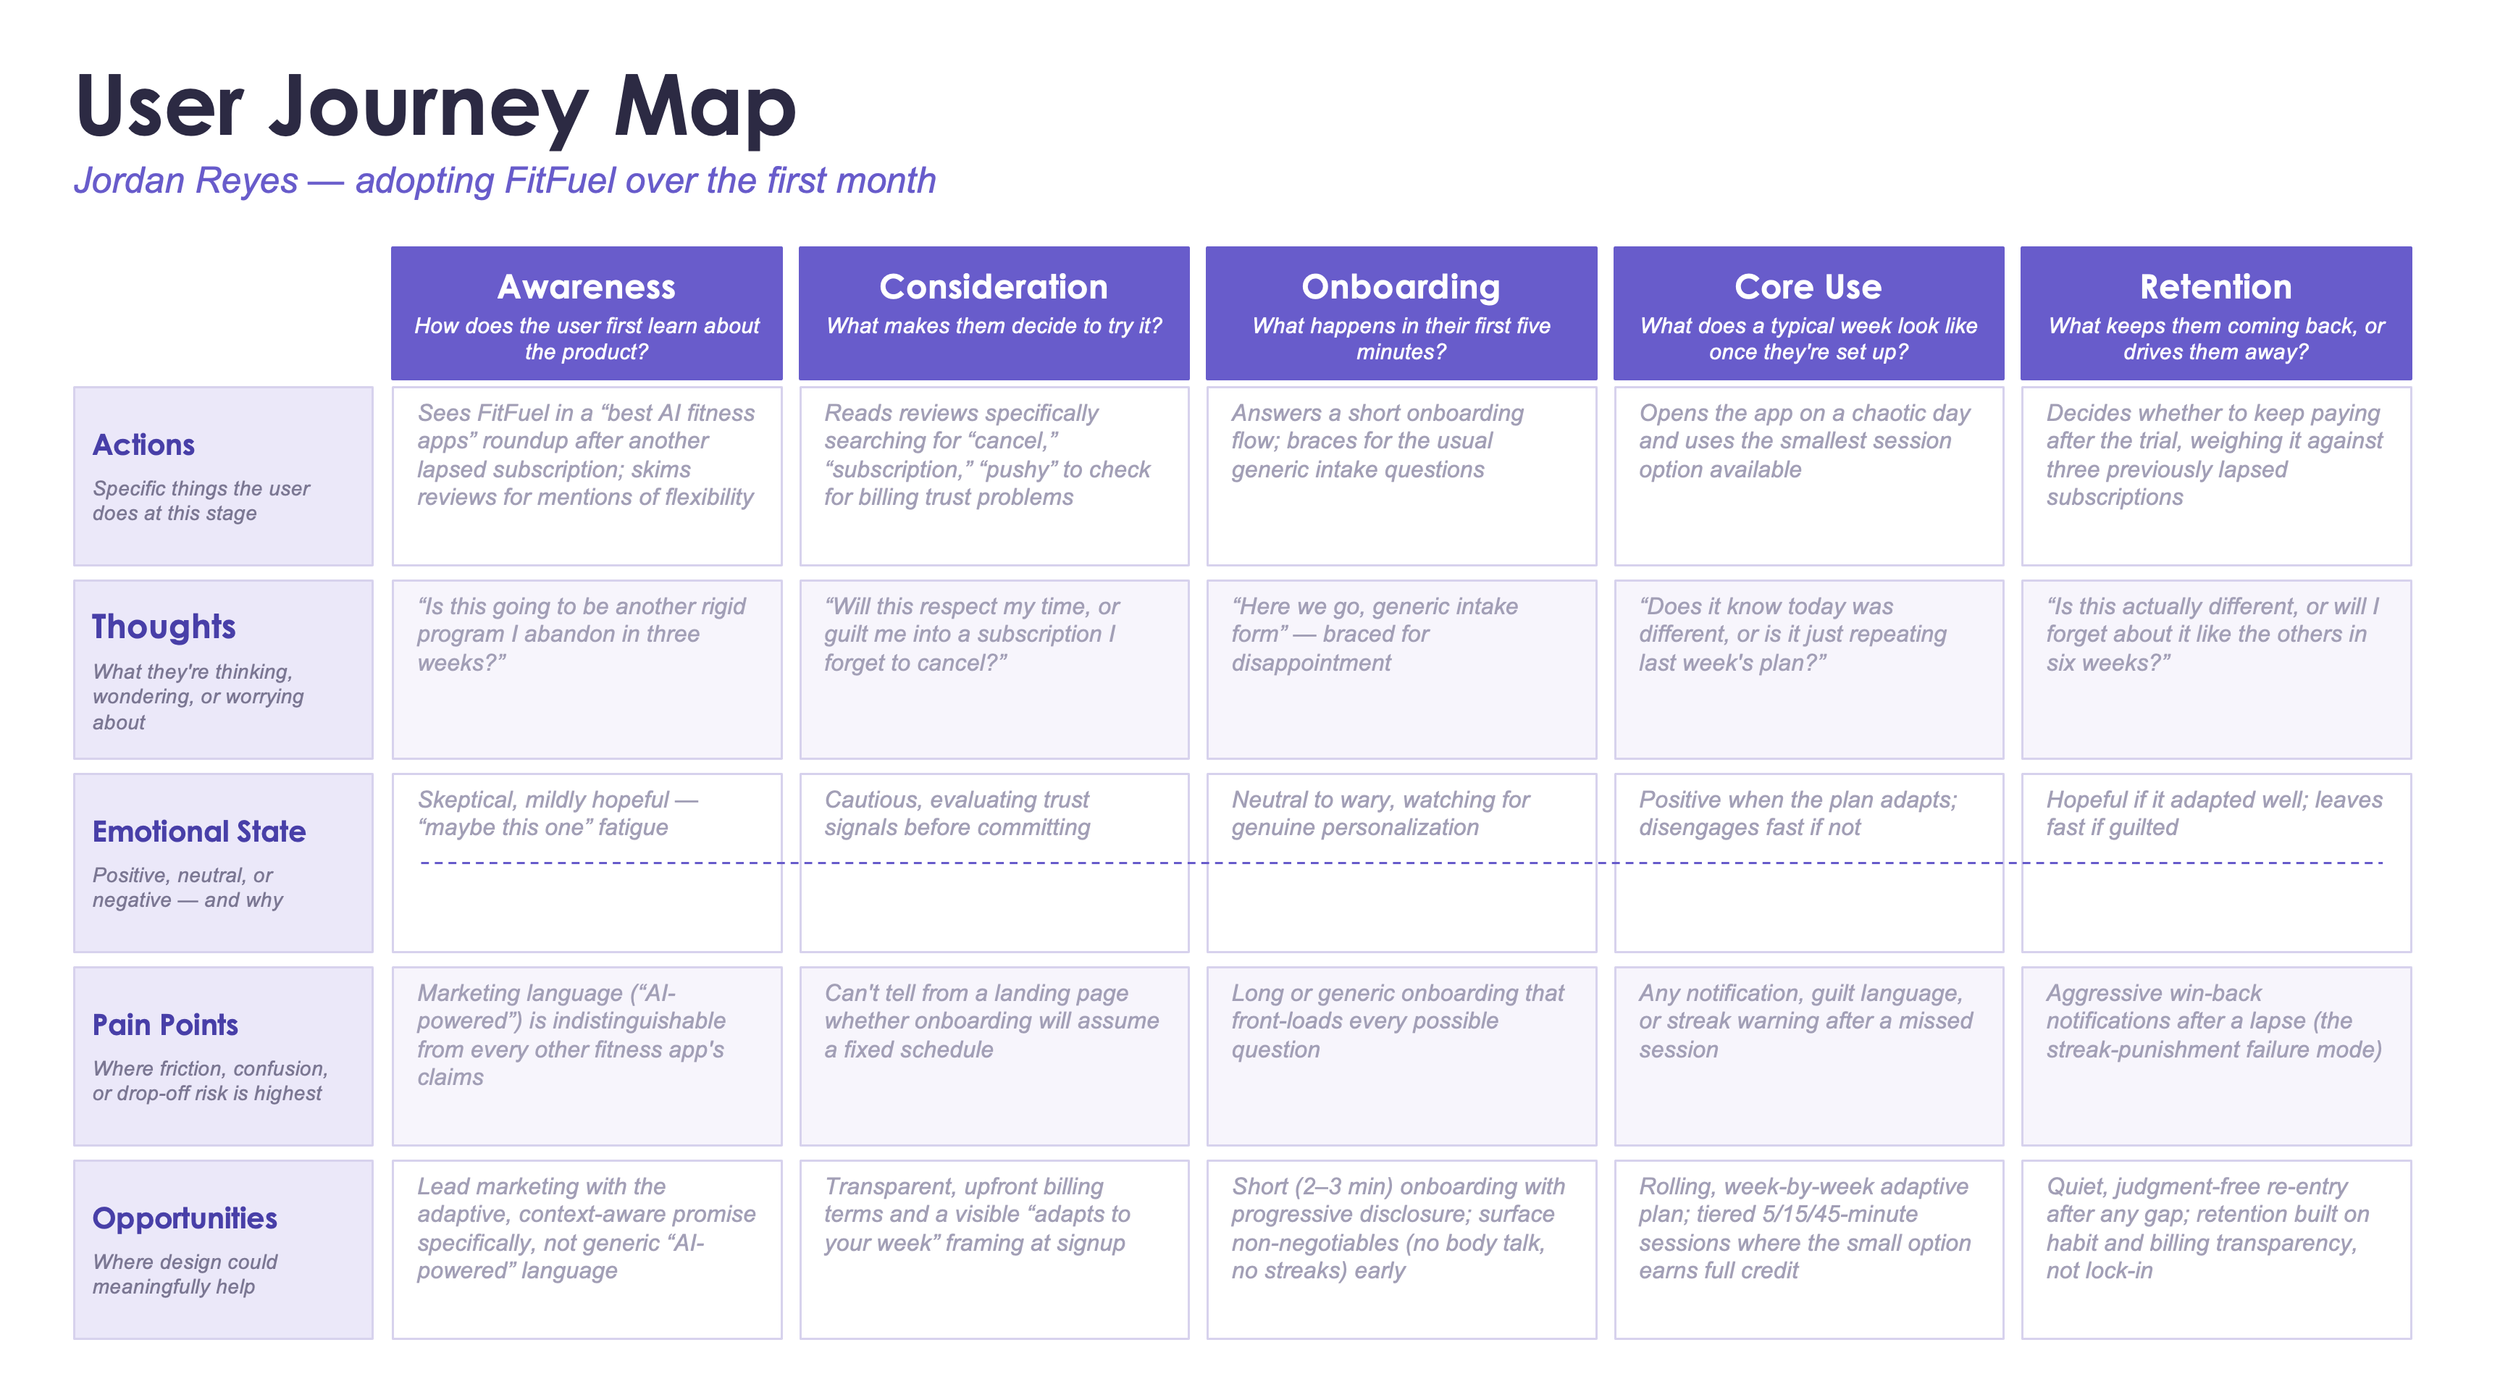
I found that the map itself confirmed something worth carrying forward: Jordan's trust concerns don't start at onboarding, they start at Awareness, in the skepticism of "is this just another app I'll abandon in three weeks," and they resurface hardest at Retention, where a single guilt-driven notification is enough to undo weeks of good adaptive behavior.
I reviewed the completed map against that expectation and didn't need to send it back for revision, which told me the framework had done its job: it surfaced a real, sequenced risk (trust eroding at the edges of the journey, not just the middle) rather than a flat list of generic app-onboarding friction.
The Week 3 design brief centered on that opportunity, brought to life in an interactive prototype built in Figma Make. Working in Figma Make meant prompting it directly rather than manually placing every element, and getting the tool to actually reflect FitFuel's brand and audience took real, repeated correction.
I fed it the brand voice documentation and persona information I had developed directly, but the first outputs defaulted to a generic, bright, upbeat aesthetic, closer to a template wellness app than anything grounded in the "tired, not lazy" research or the “direct, quietly confident” voice I'd already defined. I pushed back and insisted on revisions more than once before the output actually reflected the brand instead of the tool's own defaults.A privacy issue came up along the way, too. The tool generated a section showing other people's streaks, and I removed it for two reasons: it went against the project's no-streaks principle, and it meant sharing other people's data. The takeaway for me is that AI moves fast but doesn't hold a brand's values on its own, so the research has to stay in charge of the output.
Design & Prototype
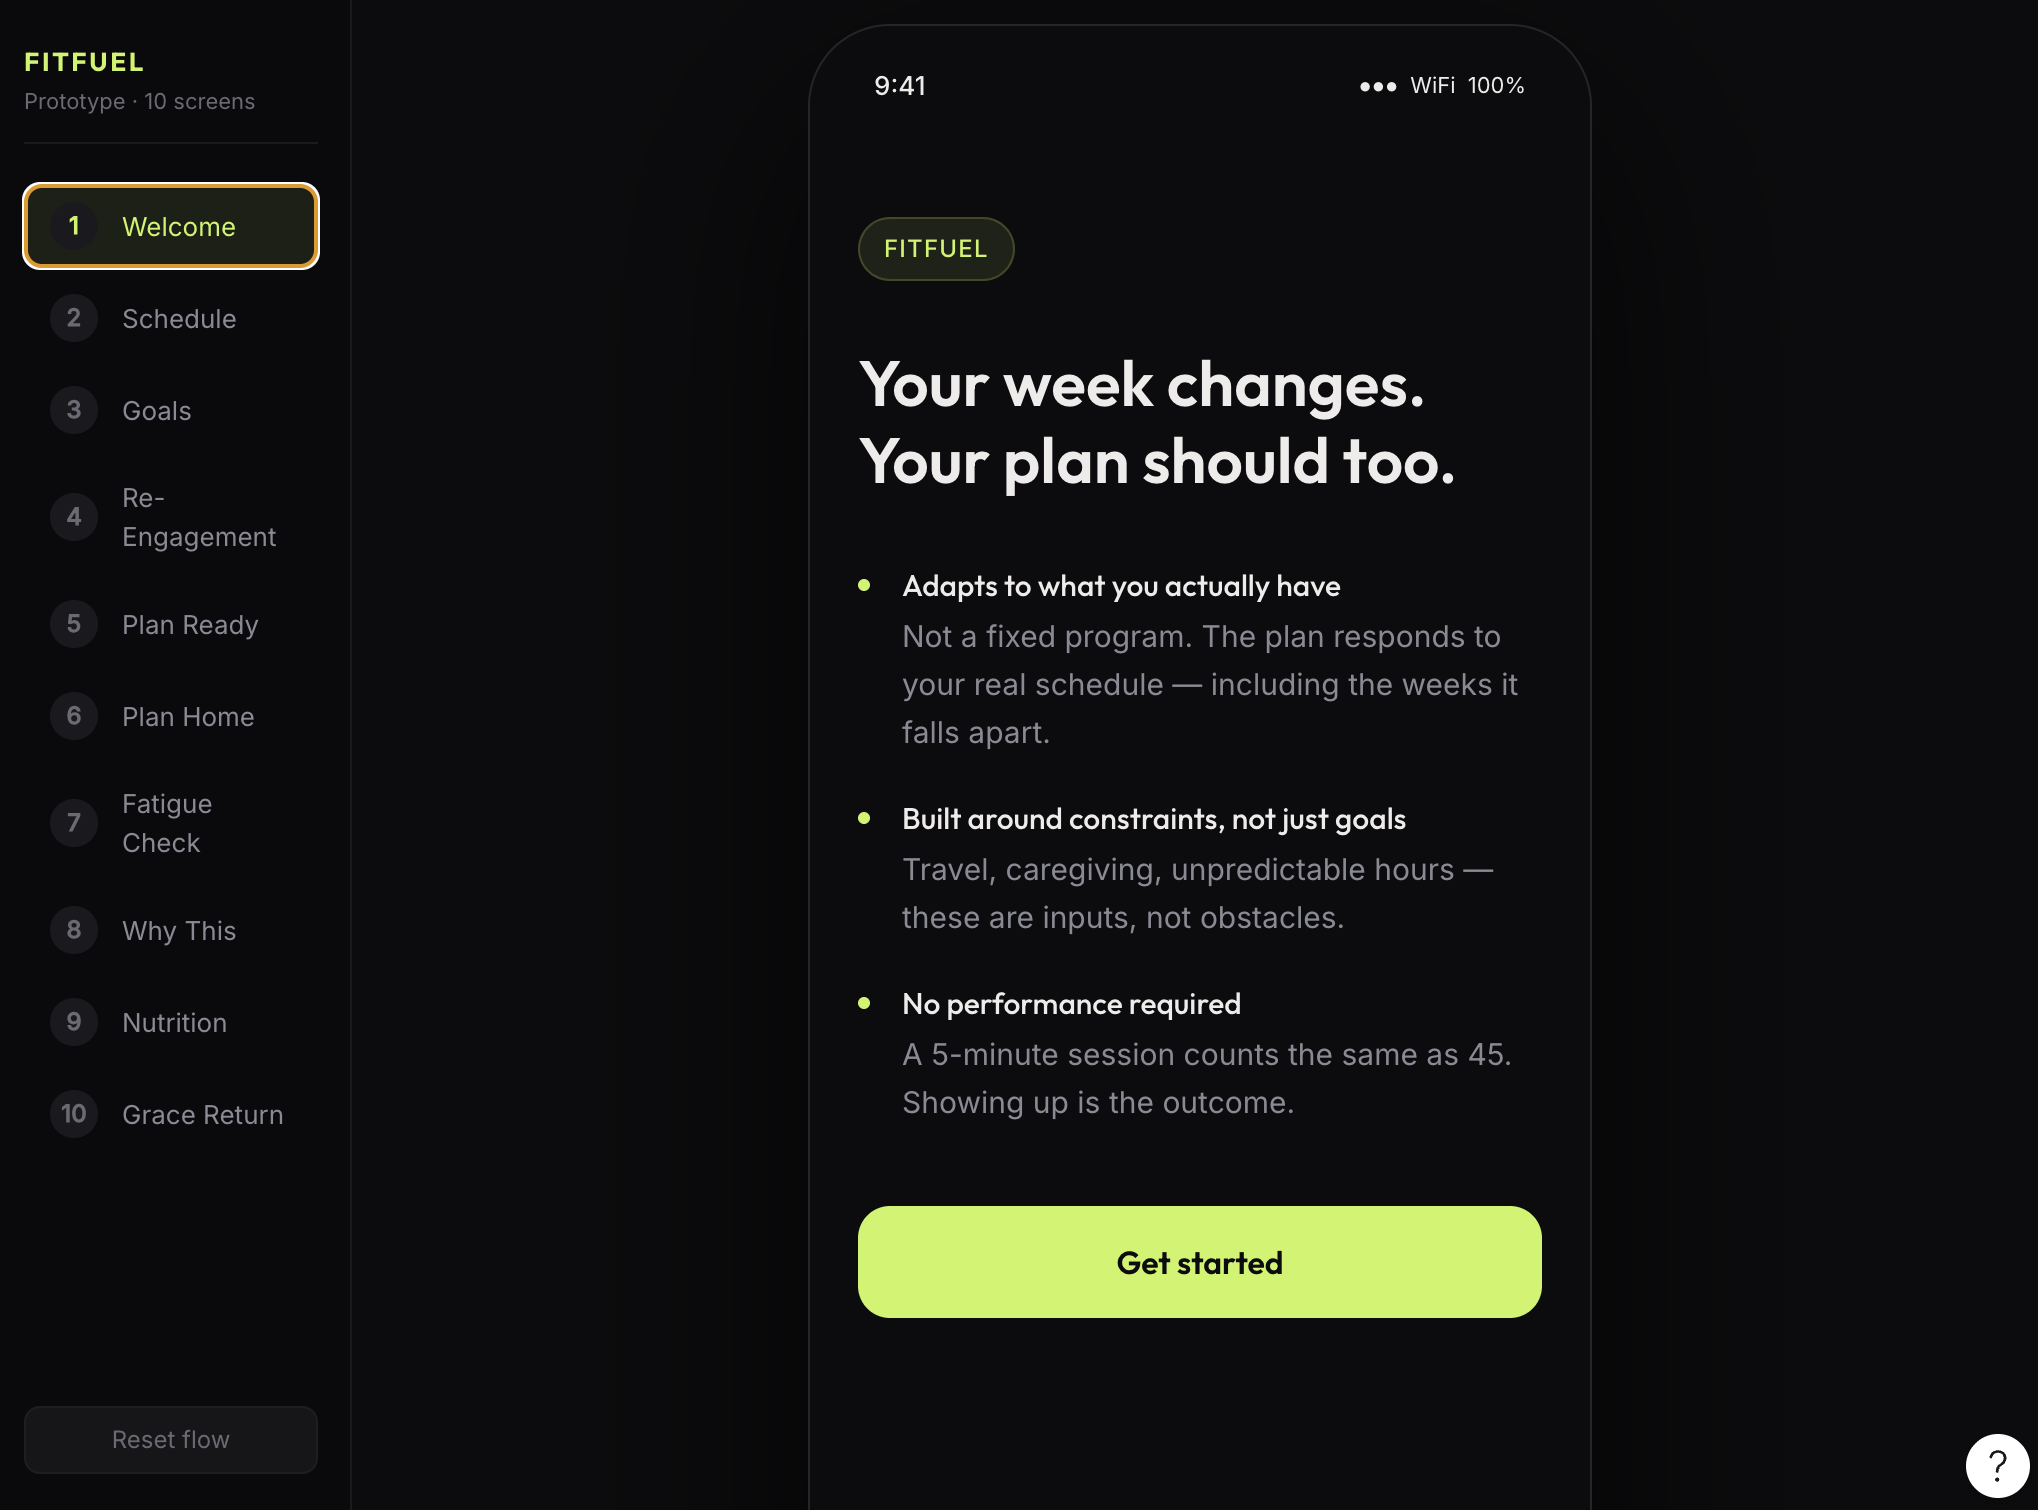
Initial AI-produced screen, ignoring user needs and brand voice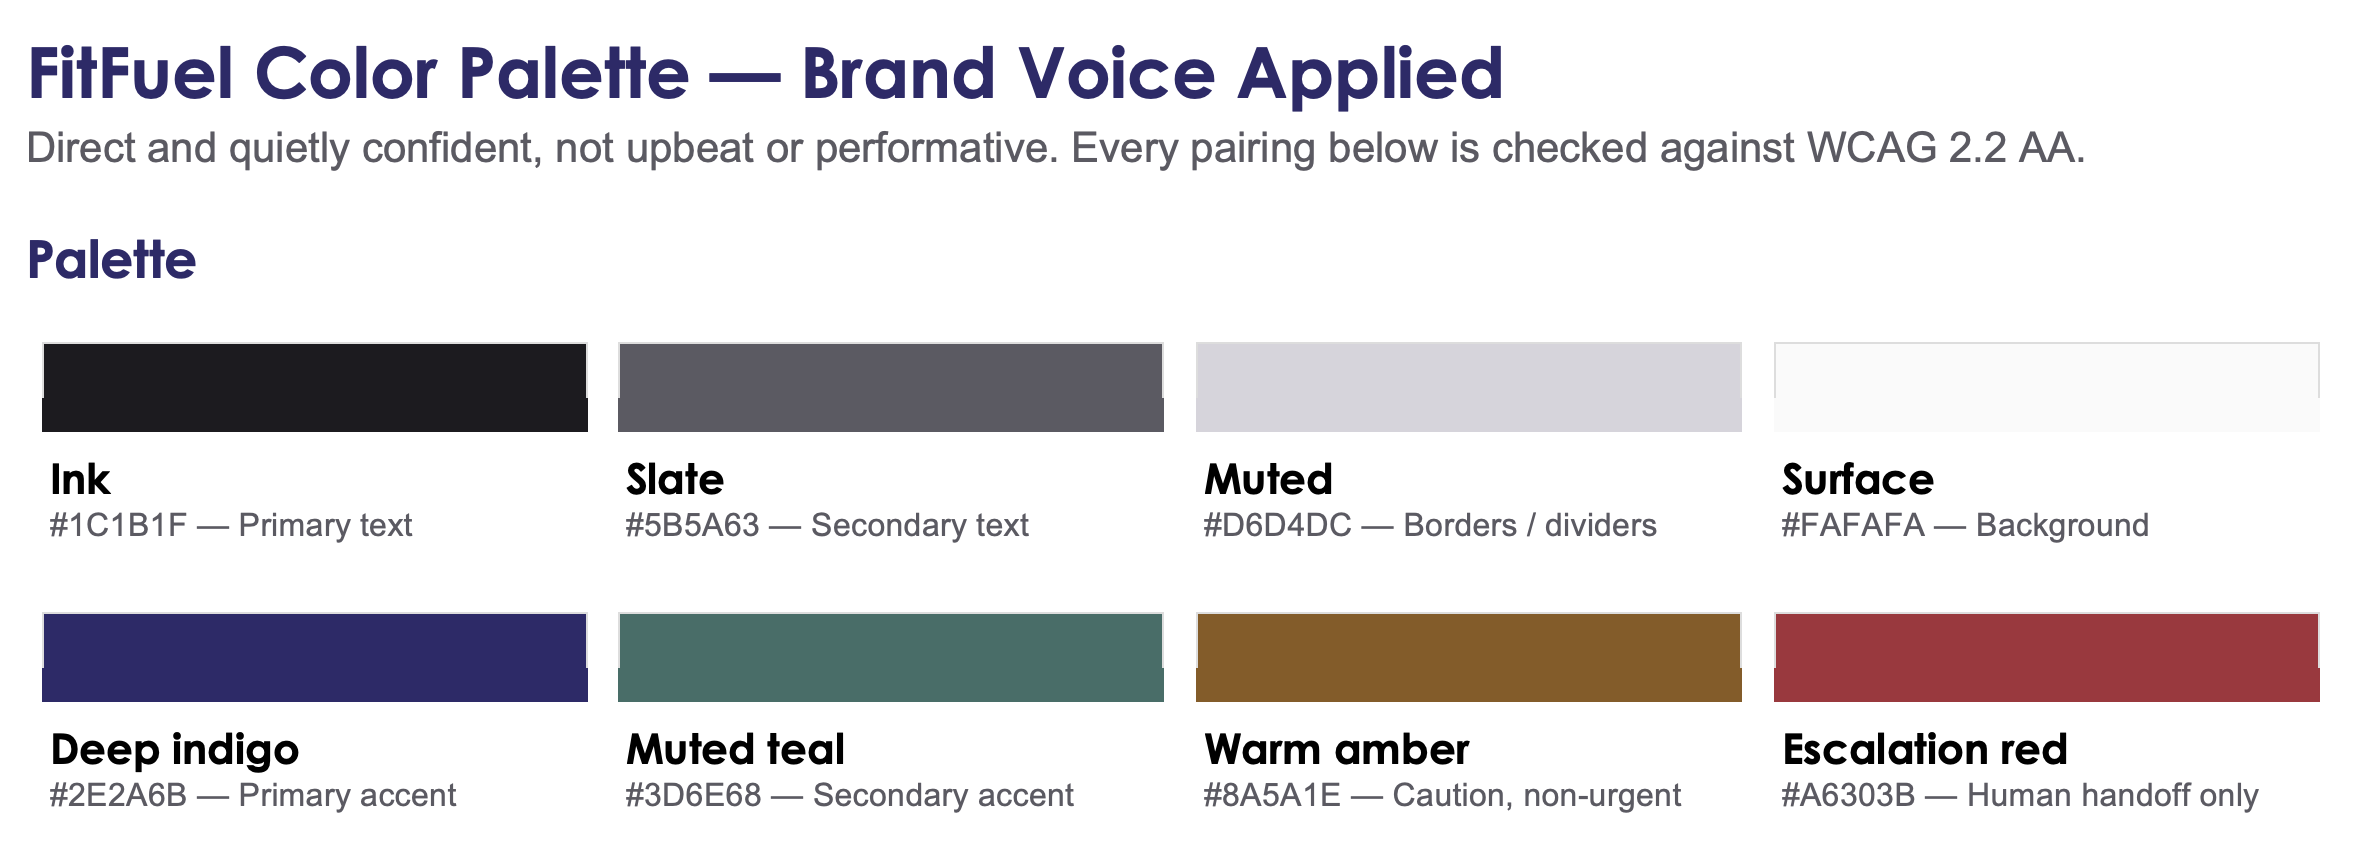
Palette developed with Claude to be utilized in prototypeImagery took a similar amount of iteration. I first tried building a background image in Adobe Firefly, but the file wouldn't import into Figma Make, which forced a change of plan partway through. That constraint turned out to be useful. Instead of designing around a fixed image, I built the visual direction from the brand itself.
Figma Make didn't generate a color system, so Claude helped produce candidate typography and color palette directions based on the brand voice documentation. I landed on "direct and quietly confident," warmth expressed through competence and respect rather than upbeat cheerfulness, a deliberate move away from the performative tone the tool defaulted to and that so many fitness apps default to as well. Figma Make wouldn't let me upload any documents, so I entered the colors manually, then evaluated the options in context before settling on a final pairing that fit the brand more precisely than the original imported image likely would have.
What came out the other side of that back and forth were decisions that each trace to a reason, not a preference.
Brand voice grew directly out of five convergent rejection patterns in the research.
Effort-tier labels ("Express / Standard / Full") were flagged and replaced. I caught this contradiction twice: it quietly implied a hierarchy of effort that fought against the "tired, not lazy" insight, so I resolved it with parity language instead.
"Next Week" forward-projection copy was removed from the reflection screen. That language added a subtle pressure working against the sustainability goal at the heart of the project, so I removed it rather than softening it.
I didn't run usability testing with real users (it was optional at this stage). What I did instead was a WCAG 2.2 AA-target accessibility audit across all 11 screens using Lighthouse and axe DevTools.
Accessibility Audit
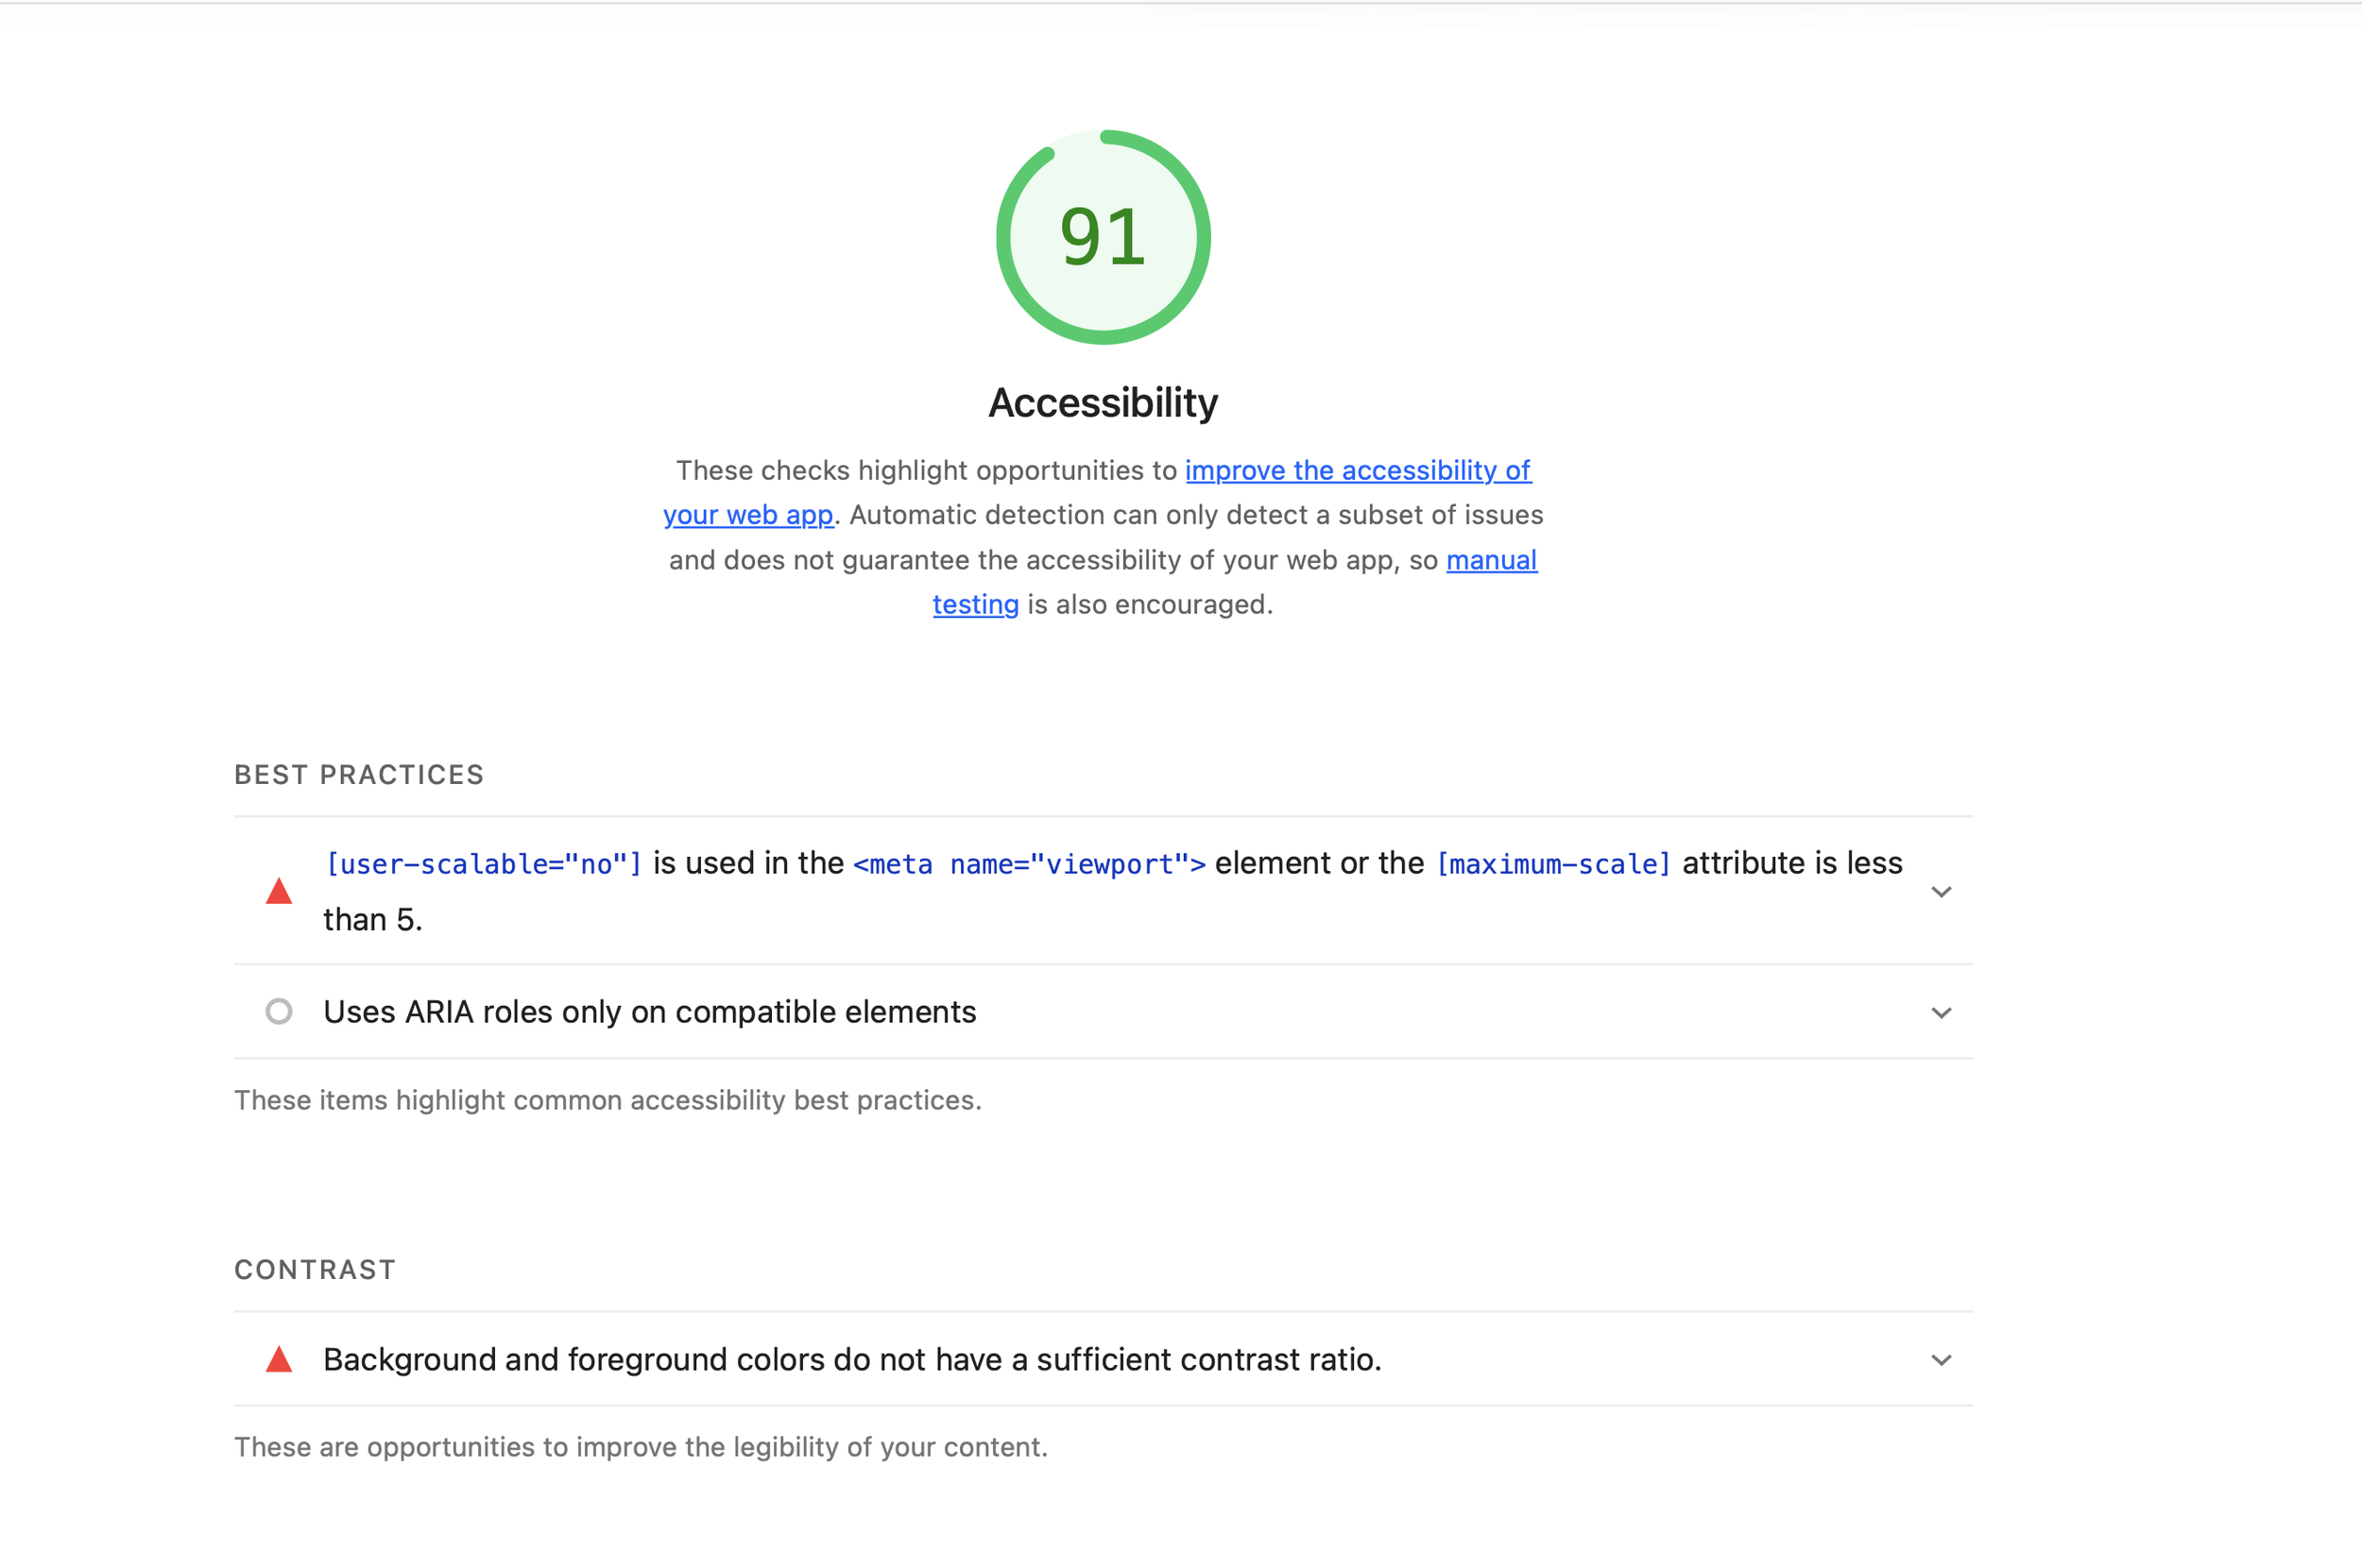
Lighthouse evaluationWhat it found
A systemic contrast failure on secondary text (about 2.75:1 against the 4.5:1 minimum), affecting text across the whole product.
Heading-styled text on two screens with no semantic heading markup, so screen-reader users miss that structure.
A sidebar contrast issue coming from the prototyping tool's auto-generated navigation. I flagged it as a tooling constraint and left it out of scope.
What's still open
The keyboard navigation pass needs a redo. My first attempt wasn't done correctly, so I pulled it.
The VoiceOver pass is partly done, and a few findings need review from someone more fluent in assistive tech.
WCAG 2.2-specific criteria (focus visibility, target size, dragging) haven't been checked yet, since axe defaults to WCAG 2.1.
AI moved nearly every stage of this project faster. It synthesized research, drafted copy, and ran accessibility scans. But almost every decision that actually mattered was a place I overrode, qualified, or reversed a first-pass AI output. The effort-tier labels, the forward-looking copy, the persona split: none of those were AI catches. My job was deciding what to trust, which is the same instinct I bring to every client relationship.
AI never functioned as a source of truth. Every validation tag, every reversal, and every recommendation traces back to my own judgment about what the evidence actually supported. The return on that shows up less in hours saved and more in what a solo practitioner was able to produce at a defensible standard: a full research report, a decision-ready design package, and a WCAG-target accessibility audit, each with a documented evidence trail, inside a three-week timeline. Next-steps include microcopy, fixing any accessibility concerns, and conducting user testing.
The repeatable part of this workflow isn't the tool, it's the discipline: tag every claim by validation status, name every reversal instead of absorbing it, and treat AI output as a draft to interrogate rather than an answer to accept.
The Reflection
Let’s Connect!
Schedule a free 1:1 virtual coffee chat with me to discuss your UX design needs.
